Friday, January 02, 2009

Zones, multiple interfaces, and routing

Some things are reasonably obvious in hindsight. This was one of them.

I've been consolidating some old applications into zones on a Solaris server.

Some of them were on physical servers, some were already in zones on other hardware. It turned out that the applications I was consolidating lived on two different subnets, and I didn't really want to go to the trouble of changing IP addresses.

No problem. The T5140 I was using has multiple interfaces, so I connected one of the unused interfaces to the second subnet and gave it an address (the server's primary interface was already in the first subnet I was using).

Then configure up the zones, remembering that you need to choose the correct network device depending on which subnet the zone is in.

And the zones didn't work. Bother. What did I forget? This:

At least one of the network interfaces used by a zone needs to have a default route associated with it.

Specifically, that second network interface needs to have a default route added to it. For the main host, it didn't matter - it will route packets over whichever interface it needs to. But if a zone is only associated with the second network interface, it can't use the default route associated with the first interface.

I add routes explicitly, so just a quick manual

route add net default 10.2.3.254

to add a default route for the second interface did the trick - you can have multiple default routes and Solaris will always use the right one.

To make this permanent, just add multiple lines to the /etc/defaultrouter file.

Tuesday, December 16, 2008

End of an era

A year ago, the dominant computing platform in the Tribble household was the Sun workstation.

OK, so only one - my W2100z - was anything like modern, with an old Sun Blade 1500 and a couple of antiquated Sun Blade 150s used by the children.

Over the summer, the Sun Blade 150s got retired - one replaced by the Blade 1500, the other by a new laptop.

Then I was fortunate enough to get a decent enough PC free, which has replaced the Sun Blade 1500.

(And don't worry, it's set up to dual boot Windows and OpenSolaris).

So I finally sold the Sun Blade 1500 today, and the house no longer has any Sparc workstations.

Monday, December 08, 2008

Solaris Link Aggregation

Setting up link aggregation in Solaris is pretty simple. First make sure you have a recent version (I'm using update 5 aka 5/08 and update 6 aka 10/08).

Then make sure your switch is configured. For example, on one of my Summit switches where I'm going to aggregate ports 7 and 8:

enable sharing 7 grouping 7 8 lacp


You can see the state of the network interfaces on the host using dladm, for example:

# dladm show-dev
nxge0 link: up speed: 1000 Mbps duplex: full
nxge1 link: up speed: 1000 Mbps duplex: full
nxge2 link: unknown speed: 0 Mbps duplex: unknown
nxge3 link: unknown speed: 0 Mbps duplex: unknown


Then on the host (connected to the console - trying to do this over the network is obviously going to be difficult), take down the existing interface:

ifconfig nxge0 down unplumb


Create an aggregate out of nxge0 and nxge1, with index 1 (why normal interfaces start out with index 0 and aggregations start out at 1 is one of those oddities):

dladm create-aggr -P L2 -l passive -d nxge0 -d nxge1 1


And then bring the interface up:

ifconfig aggr1 plumb
ifconfig aggr1 inet 172.18.1.1 netmask 255.255.255.0 broadcast 172.18.1.255 up
and then rename /etc/hostname.nxge0 to /etc/hostname.aggr1 so the right thing happens next boot.

Here I've enabled LACP (the '-l passive' flag). I'm not absolutely sure how vital this is, but I think the switch and the host need to be set compatibly.

I had a little play with the policy. In the command above it's set to 'L2'. This didn't work well for me - all the traffic went down one of the links. Same with 'L3'. Setting to to use both L2 and L3 seemed to work better

dladm modify-aggr -P L2,L3 1
and I got traffic using both links, and an aggregate throughput obviously in excess of a single gigabit.

Monitoring the aggregate can again be done using dladm. For example, you can watch the traffic and how much goes down each link with 'dladm show-aggr -s -i 1'.

T5140 trouble

Had a bit of fun and games with a T5140 last week.

This was a new machine (although when I say new, we purchased it a little while ago).

Powered on, and the preinstalled Solaris just panics. Not necessarily a problem, as I reinstall anyway. But I have seen this a few times - the preinstalled system should at least boot.

So I boot using Solaris 10 10/08, and it dies on me:

Fast Data Access MMU Miss

Not good.

What I has to do was install Solaris 10 5/08, update the system firmware, and then install the version of Solaris I wanted.

(Which explains why my other machines are fine - they were first installed a little while ago, so has S10 5/08 on them initially. But it looks as though updating to reasonably current firmware is a really good idea.)

Tuesday, October 28, 2008

Scaling administration

Commenting on my last SolView post, somebody asked a question I had asked myself:
does it gracefully handle the situation where you have thousands of zfs files systems?
And I don't actually know - because I haven't actually tried it.

The original code got the list of zfs filesystems by calling zfs list (which is now all it does) and then retrieved all the properties for each one - whether you viewed them or not. I soon scrapped that loop, as it was obvious that it doesn't scale. So I think my code is about as efficient as it can be - it's going to scale as well as the underlying tools do.

However, one of the things I've given some thought to - and one of the reasons for writing SolView in the first place - is how to get a handle on systems as they scale up. I'm not talking about managing large numbers of systems (that's an entirely separate problem), I'm talking about looking at a single system where the number of instances of an object may be measured in the tens, hundreds, or thousands.

For example, my T5140s have 128 processor threads. I have systems with 100 virtual network interfaces. Many people have systems with thousands of zfs filesystems. Zones encourage consolidation of multiple application onto a single system (so do other virtualization technologies, but in those other cases you tend to manage the instances independently), so you maybe looking at a system with dozens of zones and thousands of processes running. A thumper has 48 disks, and that's small. Using SMF, a machine typically has a couple of hundred services.

The common thread here is that the number of objects under consideration is larger than you can fit on screen (or in a terminal window, at any rate) in one go. And is thus larger than you can actually see at once. How does your brain cope with reading the output from running df on 10,000 filesystems?

As we move into this brave new world, we're going to need better tools in the areas of sorting, aggregation, and filtering.

A couple of examples from SolView and (originally) JKstat:

I wrote a lookalike of xcpustate for JKstat. That works great on my desktop. But my desktop isn't big enough to show a copy of it running on a T5140, so I wrote an enhanced version (now shipping with SolView) that shows the aggregate statistics for cores and chips, and allows you to hide the threads or cores, which makes the amount of information thrown at your eyeballs at any given time rather more manageable.

Another example is that the original view of SMF services in SolView was just a linear list. I then wrote a tree view, based on the (apparently) hierarchical names of the services. I found that the imposition of structure - even a structure that's mostly artificial - helps the brain focus on the information rather than be overwhelmed by a flat unstructured list. And that structure breaks the services down into chunks that are small enough for the user to handle easily.

So back to the example of huge numbers of ZFS filesystems. So the plan is to show them in the display grouped in the same hierarchy as the filesystems themselves, rather than as a plain list. And to show snapshots as children of their parent filesystem. So everything possible to break things down into more manageable chunks.

This relies on the underlying data being structured. I'm assuming that when someone has 100,000 filesystems that they are structured somehow - whether by department or hashed by name or whatever - rather than being a great unstructured mess. I can't create order out of chaos, but the tools we use should do everything they can to use what order they can find to create a structure that's easy to comprehend.

Monday, October 27, 2008

SolView moves ahead

I've been working on a few new features in SolView, and it's about time for a new release. So that's version 0.45 out of the door.

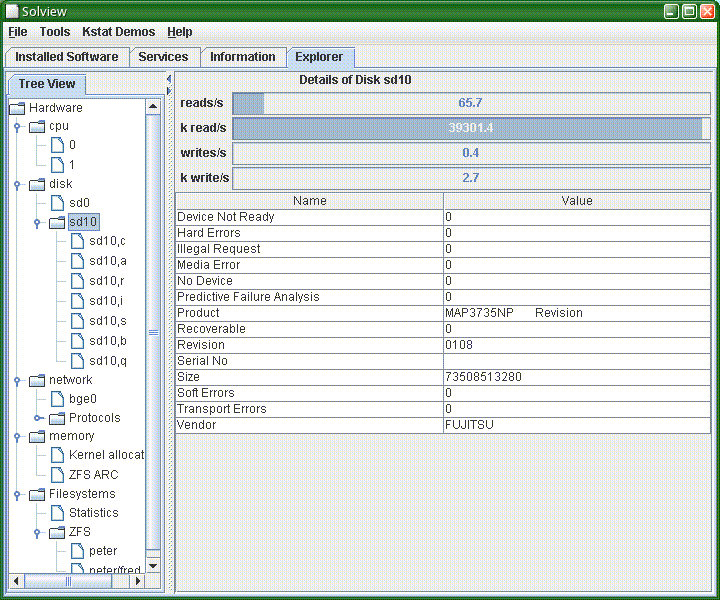
The major feature this time is a sneak peek of a prototype I've put together for the System Explorer. See the image here for a sample:


You can see the left hand panel containing a tree view of the various bits of the system that SolView has found. Selecting any of them show whatever information I can find - either by running external commands, or by using JKstat to grab statistics.

This is both skeletal and a prototype. But it does try to answer the question: what's in my system, and how do the bits relate to each other? It's the relationships that I'm trying to capture: so I have a disk, but what's it used for, and where's the load on it coming from? And there's clearly a lot more to do in this regard.

Sunday, October 26, 2008

MilaX - Wow!

I've been playing around on my laptop today. It's a fairly basic model - with a pretty large screen - that I normally just use for simple connectivity. So the fact that it's running Vista doesn't bother me, as it can launch firefox, VNC, and putty just fine.

I wanted to play around with OpenSolaris on it, which is a bit tricky - it doesn't work right on the metal (I can manually get the wired network to function, but never got the wireless going). So I'm back to running stuff under VirtualBox. Which would be easy if I had a decent amount of memory to play with, but the laptop has 768M and Sun's OpenSolaris distro needs pretty much all of that, so it's not going to work.

Enter Milax. Not only is the download tiny, but it claims to boot graphically in 256M, and CLI in 128M. So I gave it 384M in VirtualBox, and it works just fine!

It's a fabulous little distro. There's no room in that footprint for all the bloat we're used to - no desktop environment, no office suite, no java - but it works, and is really very slick.

In many ways I feel right at home: a standalone window manager and individual applications, all very lightweight, and reminds me of the energy of the 90s before the big desktop environments turned computing into a desolate wasteland.

Monday, October 20, 2008

Refactored JKstat

As I mentioned about a month ago, both JKstat and SolView were in line for some major refactoring.

I've done a bit of a spring clean on JKstat, so there's a new version - 0.25 - which has a lot of the cleanups and shuffling about that I had in mind. The class hierarchy has been restructured, code cleanup continues, and the more complex demos have been moved to SolView. The restructuring also allows the easy construction of a jar file containing just the API, so you don't need to drag in all the bloat associated with the browser, gui components, and demos.

The associated SolView release will follow shortly.

And thanks to Mike Duigou for a bunch of helpful fixes and suggestions!

Wednesday, September 24, 2008

Would you pass?

Sun have made some free pre-assessment tests available.

Just for fun, I went through the UNIX Essentials one. Would I pass? (Given that I have never had any formal training and have a rather eclectic skills mix it's not a foregone conclusion.)

According to the test, yes. I got a whopping 37/42 which is clearly enough to pass.

I suspect, though, that this says more about the accuracy (and grammatical validity, in one case) of the questions. One of the questions was incapable of being parsed into english, and I had to guess at random. Another one had two possible correct answers depending on factors you weren't told about. Another one had no correct answer on a vanilla Solaris system. There were a couple of questions that I looked at and thought to myself 'you wouldn't ever do it like that'.

(Plus a couple of questions on stuff that I would never use under any circumstances. I had a similar test when I applied for my current job, and my answer to every question mentioning vi was ':q' and use a proper editor.)

I tried the SCSA sample tests - scoring a little better on the part I test, and slightly lower on the part II. But again, there were questions that were simply wrong; some where the correct answer would always be 'look it up in the man page'; some artificially contrived questions; and I'm more than a little concerned about the coverage and subject matter. And on the SCSA tests there are a couple of areas where I haven't done much for a few years now (my OBP and LDAP skills are obviously getting a little rusty).

Tuesday, September 23, 2008

On OpenSolaris Change

When I noted that Sun's plans for OpenSolaris threatened the Solaris ecosystem, I got a mixed bag of comments.

Some of the comments missed the point, which is that compatibility (across the board) is a key strength, and that producing something that forces what is essentially a new platform on the world will drive away old customers without necessarily attracting new ones.

The key point is compatibility. And while modernization is essential (I'll come back to that later), it is possible to do it compatibly, in an evolutionary manner, rather than doing a rip and replace job.

Evolutionary change allows you to keep existing customers who thus have an easier migration path; makes it easier for new adopters who can tap into the existing skills pool; and allows the improvements to be fed back to older (ie. current, such as Solaris 10) releases which still have a long service life ahead of them.

Replacing the packaging system and installer from scratch is just something you should never do. It's probably cost the Solaris/OpenSolaris ecosystem about 2 years, and we can only hope that we can eventually recover in the way that Firefox did after Netscape's mistake.

Saturday, September 20, 2008

Too radical a change?

Attempting to predict the future is difficult, but what I do know about Sun's plans for Solaris and OpenSolaris fills me with concern.

What we seem to be looking at is an OpenSolaris derived replacement for Solaris. Which means a completely replaced packaging system and installer. Being essentially incompatible with what we currently have, this means a fork-lift upgrade: you can't simply go forward as you are before.

Forcing change upon customers is bad. It makes the upgrade a decision point, and customers are then forced to make a choice. So what might customers do? Let's consider some classes of customer:

Solaris-only shops: they have to go from what they have to something different. So given that they have to change, some might take the replacement; I suspect many will choose something different.

Heterogeneous shops: many large shops are heterogeneous, and already support multiple platforms. I see significant resistance to adopting any new platforms, and many shops will simply migrate to one of their existing platforms rather than adopt a new one.

Alien shops: there's going to be problems getting a new platform into a shop that doesn't already use Solaris. Solaris is mature, well tested, has a reasonable number of practitioners available in the job market. An OpenSolaris based platform may be unattractive to such shops: not only would they be unable to bring in expertise for something new, but Sun are advertising it as just the same as Linux, so why would they change to something that isn't different?

So, as I see it, scrapping Solaris and replacing it with a fundamentally different OpenSolaris distribution is going to drive a fraction (possibly quite a large fraction) of the existing Solaris base to other platforms, and I simply can't see any corresponding takeup of new deployments.

Contrast this with the story if you take the existing Solaris and produce a new version (Solaris 11 would be the obvious numbering) that uses the same packaging, installation, deployment, and administration tools as the existing Solaris. In other words, that could be deployed painlessly and seamlessly without any need for additional training or rebuilding new administrative infrastructure, but contains all the advancements that have been made to OpenSolaris in the last 4 years - things such as CIFS client and server, Crossbow, NFS enhancements, and an updated desktop just to name a few. Existing users would simply adopt it as a logical progression; new users would be more attracted because they could concentrate on the technical features and would be able to take advantage of the pool of experience available to deploy it.

The problem is simply one of change. The technical merits of the old and new systems are essentially irrelevant to the discussion. Given how dangerous change is, why is OpenSolaris so insistent on rip and replace rather than improving and enhancing what we already have?

Tuesday, September 16, 2008

Better documentation style

I don't write as much documentation as I should, and frankly what I do write often isn't done that well. But the OpenSolaris Editorial Cheat Sheet contains a lot of useful advice and hints condensed into a small space. Now, if I could just relearn my writing style my documentation wouldn't look like it was written in such an amateurish fashion!

Monday, September 15, 2008

Solaris Advantages

I make extensive use of Solaris, so thought it would be worth summarizing some of the key advantages that it brings for me. Other people might consider other aspects important, and you could construct similar lists for other platforms.

Compatibility - software that works on one release or for a given patch revision of Solaris is pretty well guaranteed to run subsequently. This is huge, and isn't generally true for other platforms. I've got 20-year old applications running happily day in, day out. By and large, everything just works, and continues to work.

Installation Automation - jumpstart is a huge competitive advantage. You can trivially deploy systems, being able to completely reproduce a configuration, and roll out systems and updates effortlessly.

Lightweight virtualization - Zones, especially sparse root zones, allow you to consolidate large numbers of small systems onto a server, with minimal overhead and without adding to the management overhead normally associated with adding another system to your network. (Note that the real advantage here comes from the use of sparse root zones, which not only guarantee that the zone looks like its parent, but mean that you don't manage the software on the zones at all but just manage the parent host. Whole root zones aren't as lightweight and don't have anything like the same advantages, and branded zones - while a neat trick - don't have any compelling advantages over other virtualization solutions.)

ZFS - for storage on a massive scale, combined with ease of management, and the ability to verify that your data is what you though it was, this is key. To that you can add snapshots (which we use automatically now any time we change something, which makes our backout plans for a change request way simpler than they used to be), and compression (storing text - or xml - files just got a whole lot cheaper), and it's free.

Ease of management - while Sun have generally failed completely to provide advanced management tools, the fact is that you don't need them - the underlying facilities in Solaris are pretty solid and it's trivial to write your own layer of tools on top, and integrate Solaris into a range of other tools. Not only that, but the tools are consistent - while things do evolve, you don't have to completely relearn how to manage the system on a regular and frequent basis.

Cheap - it's free, and not only that but you don't have to pay for a 3rd-party virtualization solution, I/O multipathing, volume manager, or filesystem, as they're all included.

Sunday, September 14, 2008

Refactoring solview and jkstat

Originally, JKstat and SolView were completely separate.

The latest released version of SolView comes with JKstat, so you can launch some of the JKstat demos.

I'm looking at much closer ties between the two. I've had a much more in-depth use for JKstat in mind all along, and the way I'm doing it is by adding what I'm calling a "System Explorer" to SolView.

So SolView will have a view of all the interesting components of a system: processors (chips, cores, and threads), memory, disks, filesystems, networks. Anything else if I can think of how to do it. And then will display pretty much everything you can about the selected object. A lot of that information is gleaned from kstats using JKstat.

From that point of view, something like the ZFS ARC demo makes more sense as a sophisticated component inside SolView rather than a standalone JKstat demo application.

So what I'm planning on doing (and this may take a while) is to have a spring clean of the demos in JKstat, removing the bad ones entirely and moving the more complex and involved ones to SolView. And then splitting JKstat into two logically separate parts: the core API (which has no graphical components), and the graphical browser with some basic demos. The two parts of JKstat will still be developed together, although I wouldn't expect that much development once the process is complete, as JKstat will be stable and the higher-level fancy tools will be developed independently under the SolView banner.

Friday, September 05, 2008

How to confuse ImageMagick

I mentioned some huge files generated by ImageMagick.

I worked out what was going wrong. What we do is take a 600dpi original and generate a bunch of images at different resolutions and formats. Looking at the headers:

Software: Adobe Photoshop CS2 Windows

That's odd. Someone has fiddled with the image.

Image Width: 2943 Image Length: 4126

Hm. Not so bad.

Resolution: 0.393, 0.393 pixels/cm

Yikes! If my calculations are correct that's 1 dpi.

So when I resize it to 300 dpi I end up trying to create a 882900x1237800 image. 10^12 pixels. No wonder it can't cope.

Moral of the story: never trust your input data.

Thursday, September 04, 2008

When to bury the pager

If anyone's been following me on twitter recently you may have noticed a few fraught messages about SANs and pagers.

We have an on-call rota. Being a relatively small department, this actually means that we cover the entire department - so it's possible that I might get a call to sort out a Windows problem, or that one of the Windows guys might get to sort out one of my Sun servers. But it's not usually too stressful.

This last week has been a bit of a nightmare and the problem has been so bad and so apparently intractable that I've simply buried the pager, turned off notification of email and texts on the phone, and relied on someone phoning me if anything new came up. Otherwise I would get woken up several hundred times a night for no good purpose.

Of course, today being the final day of my stint (yay!) I finally work out what's causing it.

What we've been having is the SAN storage on one of our boxes going offline. Erratically, unpredictably, and pretty often. Started last Friday, continuing on and off since.

This isn't the first time. We've seen some isolated panics, and updated drivers. They fix the panic, for sure, but now it just stays broken when it sees a problem. The system vendor, the storage vendor, and the HBA vendor got involved.

We've tried a number of fixes. Replaced the HBA. Made no difference. Put another HBA in a different slot. Made no difference. Tried running one port on each HBA rather than 2 on one. Made no difference. We're seeing problems down all paths to the storage (pretty much equally).

Last night (OK, early this morning) I noticed that the block addresses that were reporting errors weren't entirely random. There were a set of blocks that were being reported again and again. And the errors come in groups, but each group contained one of the common blocks (presumably the other were just random addresses that happened to be being accessed during the error state).

I've had conversations with some users who've been having trouble getting one of their applications to run to completion with all the problems we've had. And they're getting fraught because they have deadlines to meet.

And then I start putting two and two together. Can I find out exactly when they were running their application? OK, so they started last Friday (just about when the problem started). And we know that the system was fine for a while after a reboot, and going back it turns out that either a plain reboot, or a reboot for hardware replacement, kills whatever they're doing, and it may be later in the evening or the next morning before they start work again.

So, it's an absolutely massive coincidence - an almost perfect correlation - that we have problems that kill the entire system for hours an hour after they start their applications up, and the problems finish within seconds of their application completing a task.

So, it looks very much like there's something in their data that's killing either the SAN, the HBA, or the driver. Some random pattern of bits that causes something involved to just freak out. (I don't really thing it's a storage hardware error. It could be, but there are so many layers of abstraction and virtualisation in the way that a regular bad block would get mangled long before it gets to my server.) And it's only the one dataset that's causing grief - we have lots of other applications, and lots of servers, and none of them are seeing significant problems.

So, we can fix the problem - just don't run that thing!

And then I realize that I've seen this before. Now that's on a completely different model of server running a different version of solaris running a different filesystem on different storage. But it's files (different files) but from the same project. Creepy.

Thank heaven for sparse files!

We use ImageMagick to do a lot of image processing. I'm not sure what it's up to, but some processing needs to create temporary working files that can be quite large (in /var/tmp by default, I've moved them with TMPDIR because that filled up).

However, I now see this:

/bin/ls -l /storage/tmp
total 203037932
-rw------- 1 user grp 169845176062560 Sep 4 11:18 magick-XXT0aaXE
-rw------- 1 user grp 222497224416 Sep 4 13:24 magick-XXU0aaXE
-rw------- 1 user grp 11499827272024 Sep 4 13:11 magick-XXbFaiKF
-rw------- 1 user grp 15064771904 Sep 4 13:24 magick-XXcFaiKF
-rw------- 1 user grp 18904557170048 Sep 4 10:51 magick-XXtlaGCE
-rw------- 1 user grp 24764978480 Sep 4 13:24 magick-XXulaGCE

or, in more readable units a few seconds later:

/bin/ls -lhs /storage/tmp
total 203038194
33272257 -rw------- 1 user grp 154T Sep 4 11:18 magick-XXT0aaXE
34295031 -rw------- 1 user grp 207G Sep 4 13:24 magick-XXU0aaXE
29432967 -rw------- 1 user grp 10T Sep 4 13:11 magick-XXbFaiKF
9271301 -rw------- 1 user grp 14G Sep 4 13:24 magick-XXcFaiKF
48382483 -rw------- 1 user grp 17T Sep 4 10:51 magick-XXtlaGCE
48384155 -rw------- 1 user grp 23G Sep 4 13:24 magick-XXulaGCE

Ouch. That's on an internal 146G drive.

What on earth is it doing with a 154 terabyte file?

Thursday, August 28, 2008

JKstat meets the ZFS ARC

Recently, Ben Rockwood posted a useful script to display ZFS cache statistics.

Now, all it's doing is grabbing kstats, so it wasn't much of a stretch to put together a new version of JKstat that has a new demo to display the ZFS cache statistics. Try

jkstat arcstat
.
(Requires OpenSolaris, Solaris Nevada, or Solaris 10 8/07 or later to actually have the kstats to display.)

This release of JKstat is a bit rough, as there are a few other things I was working on that aren't neatly finished off yet, but I thought it worth putting out just for the arcstat demo - any comments and suggestions for improvement would be gratefully appreciated!

So, download JKstat now - and here's a little snapshot of the new demo:

Wednesday, August 27, 2008

Computers - unpredictable creatures

Computers are unpredictable beasts. You would think they would be more deterministic, but reality is otherwise.

I have a server with a tape drive. We've used it for about a year, most days. Then suddenly we start getting errors. At first we thought it was a bad tape, but then multiple tapes started giving us grief. Easy enough, just use a different drive. I finally got around to debugging it last week. Swapped the drives over - still errors. Turned out to be a bad cable. That's a new one - I've not seen a SCSI cable fail like that before. (Usually they fail straight away or when you change something, not after working stably and untouched for the best part of a year.)

Yesterday I set up SNMP on some machines for monitoring purposes. Pointed the monitoring system at them, and a couple of minutes later a couple stop responding. That wasn't part of the plan. So I go to the LOM interface, and they're powered off. Call the datacenter, they haven't done anything. I have seen strange things, but snmp (running unprivileged, I might add) powering a machine off when queried? So I tell them to power themselves back on. One comes up fine, the other boots but no ZFS filesystems or zones. I try format. No SAN disks. And then:
# fcinfo hba-port
No Adapters Found.
Yikes! It had a couple of fiber-channel HBAs in it a few minutes ago.

I still don't know what happened, but some electrical gremlins had gotten into the works. So the machines had obviously shut themselves off due to lack of power. And I'm guessing that the PSUs were capable of supplying just enough power to boot the machine, but not enough to get the HBAs powered up properly. Another new failure mode to go in the book.

Saturday, July 05, 2008

The gardening release

I've been developing SolView and JKstat for a while. Over time, code goes stale so I thought it was time for a good cleanup.

Rather than trying to spot all the bad code by eye, I sought a tool that would find unused code, unused imports, and generally find problems automatically. (And I already run javac with the -Xlint:unchecked flag, and use the OpenSolaris jstyle utility.)

After a little looking around, I found PMD and find it very useful. It's done an excellent job of finding poor code. Fortunately, it hasn't found any killer bugs, but has pointed out plenty of cases where I've been sloppy. One bad habit I've got into is unnecessarily declaring class fields rather than local variables, for example. So I recommend it. (I don't regard this as the end of the exercise - I plan to keep looking to see what other static analysis tools can tell me about my code.)

As a result, I've released new versions of SolView and JKstat that have been cleaned up. I haven't done much else to JKstat, although I have enabled the ability for SolView to just show the panel you're primarily interested in (such as just the services, or the general information) which makes it rather lighter weight.